NVIDIA Blackwell GPUs
from your Elite Partner

As part of the core.two corporate group, partimus, together with primeline solutions, is an official NVIDIA Elite Partner and thus belongs to a select group of qualified providers.
Maximum GPU performance for your AI workloads
GPU Performance for AI and Visualization – available in Germany, with a fixed monthly price and no waiting list. As an NVIDIA Elite Partner within the core.two Group, we offer you the NVIDIA Blackwell generation: B300 SXM6 for large-scale training, RTX PRO 6000 SE and RTX PRO 5000 for inference and professional graphics, complemented by the proven H200 NVL. Everything is operated in our ISO 27001-certified data center in Limburg. With our Hugging Face configurator, you can find the right GPU for your needs in seconds—whether it’s for training, inference, or high-end graphics.
- ISO 27001 certified data center
- Available immediately
- Hugging Face integrated
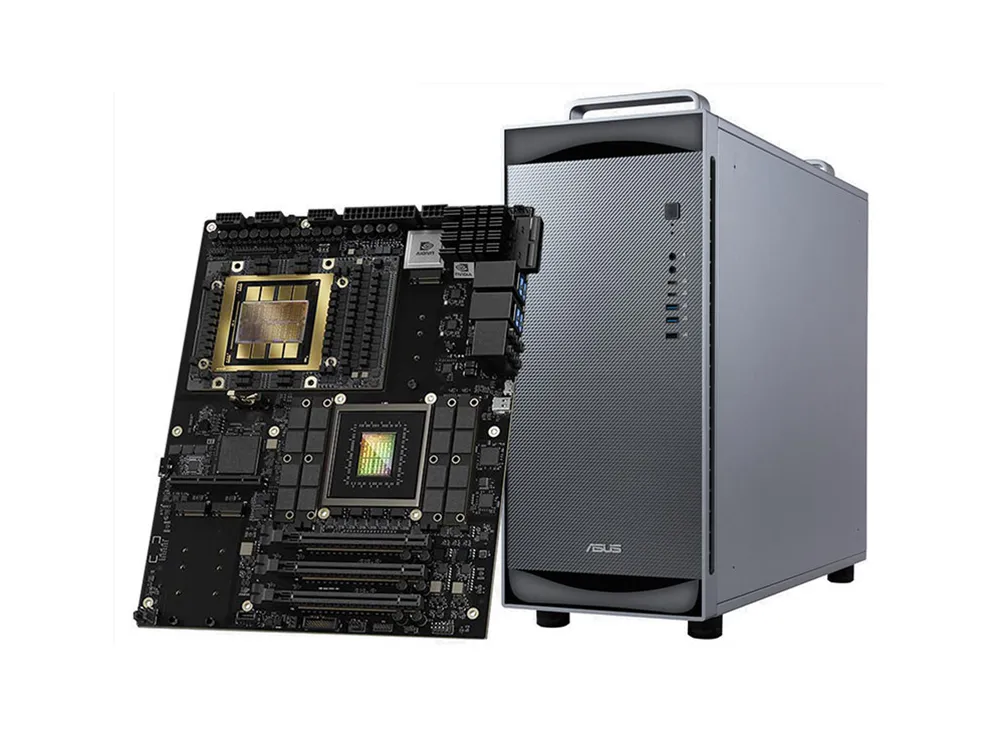
Rent an NVIDIA DGX Station
Dedicated AI workstation with NVIDIA GB300 Grace Blackwell Ultra—hosted in our data center in Limburg, exclusively for you.
Blackwell Ultra GPU | Grace CPU with 72 cores | 748 GB of coherent memory | 4 TB NVMe
| Term | Monthly price | Equals |
|---|---|---|
| 1 month | €9,417 | €12.90 / hour |
| 6 months | €8,468 | €11.60 per hour |
| 12 months | €7,884 | €10.80 / hour |
| 24 months | €7,373 | €10.10 / hour |
Configure your GPU Cloud instance now
Not big enough?
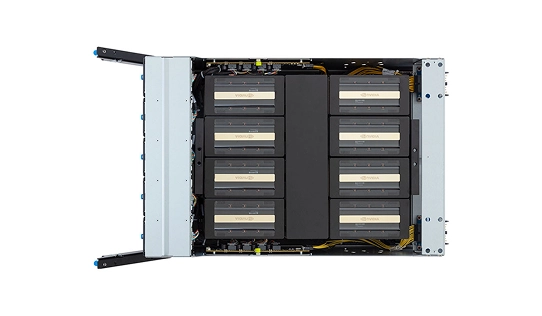
Rent a complete B300 system with
8x NVIDIA HGX B300 SXM GPUs
for only
29,500 € / month
with a term of 24 months!
CPU: 2 x AMD EPYC 9555 64C/128T 3.2GHz – 4.4GHz Turbo
RAM: 1536GB DDR5 RAM
NVME: 4x 15.36TB GEN5 NVMe
Network: 2x100G connection, as well as /28 IPv4 & /56 IPv6 network
The hunt for computing power:
Access to Blackwell & optimization for AI
Technological progress in the fields of artificial intelligence, high-performance computing and professional visualization is driving the demand for computing power to a new level. Companies, research institutions and developers are under increasing pressure to provide state-of-the-art GPUs that are quickly available, efficient to use and secure to integrate – but this is precisely where new bottlenecks arise. Are you aware of these difficulties?
- Proprietary GPU hardware ties up capital that only pays off with consistently high utilization—and the procurement and operating costs for systems such as the B300 or RTX PRO 6000 SE are considerable.
- Public cloud providers bill by the hour. For continuous training or productive inference, this can quickly become more expensive than a fixed instance —with monthly costs that are difficult to plan for.
- The efficient optimization of AI inference - i.e. the execution of trained models with low latency, high throughput and optimal costs - remains a core technical challenge.
- How do you choose the perfect GPU from the high-end portfolio for your specific Hugging Face models (training vs. inference) or demanding visualization tasks?
- Data protection and compliance (GDPR) are often a critical and difficult-to-calculate issue when using international cloud providers.
Blackwell Compute & Pro Graphics -
Available immediately from your NVIDIA Elite Partner
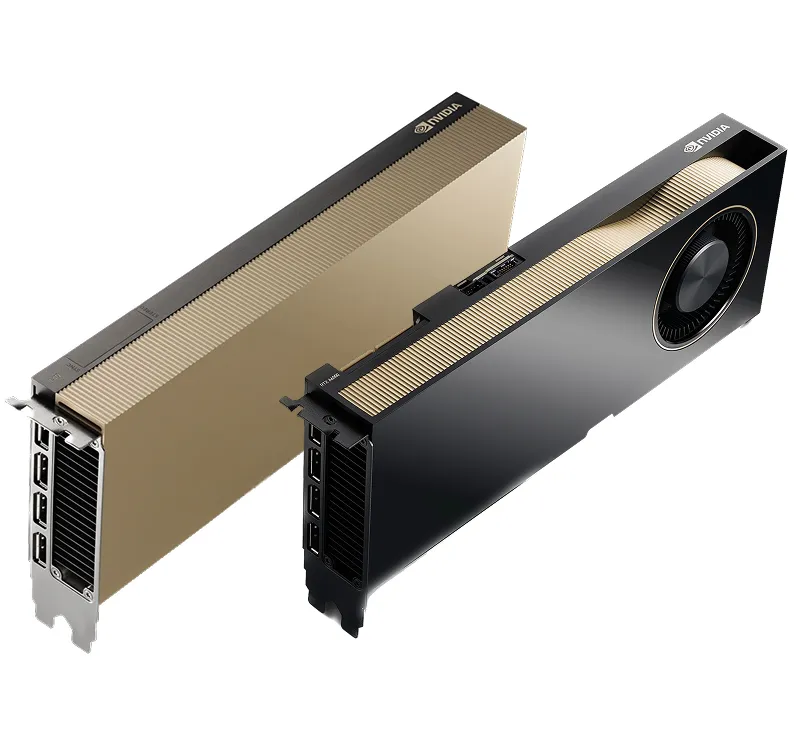
The NVIDIA Blackwell architecture is now the production-ready foundation for AI training, inference, and professional visualization. As an official NVIDIA Elite Partner and in close collaboration with primeline solutions, we provide you with the B300 SXM6, RTX PRO 6000 SE, and RTX PRO 5000, supplemented by the H200 NVL for memory-intensive inference. Whether it’s AI training, real-time inference, or graphics-intensive applications: you configure your instance, and we deploy it in Limburg—with a clear runtime and a fixed monthly price.
As an NVIDIA Elite Partner and through our partnership with primeline solutions, we cover both sides of the Blackwell generation: the B300 SXM6 compute accelerator with 192 GB of RAM and 2 TB of NVMe per instance for large-scale training and inference workloads, as well as the professionalRTX PRO 6000 SE and RTX PRO 5000 GPUs for rendering, visualization, and low-latency inference. This way, you get the right class for every workload—without having to procure your own hardware.
As a complement to the Blackwell series, we offer the NVIDIA H200 NVL. With 141 GB of HBM3e and approximately 4.8 TB/s of memory bandwidth, it is particularly well-suited for large models and memory-intensive inference—a proven, predictable option alongside the Blackwell instances. With this range of options, you’ll find the right GPU for every task: from the RTX PRO 5000 48GB starting at €900.00 per month to the complete B300 system.
Our interactive configurator takes the time-consuming search for the right GPU off your hands: Simply enter your Hugging Face model and the tool will automatically recommend the ideal GPUs - tailored to requirements such as training, inference, memory requirements and latency. This allows you to make informed decisions at the touch of a button and use your resources more efficiently.
Our entire GPU infrastructure is operated in our own data center in Limburg, which is ISO 27001 certified and meets the highest standards of data protection and reliability. Your data and models are guaranteed to remain in Germany and are processed exclusively in accordance with GDPR standards - for maximum security and compliance without compromise.
Rent NVIDIA Blackwell GPUs now
Configure your instance with NVIDIA B300 SXM6, RTX PRO 6000 SE, RTX PRO 5000, or H200 NVL—with terms ranging from one to 24 months and a transparent monthly price. Our configurator will help you make your selection. Do you have any questions? Our experts will be happy to assist you.
State-of-the-art GPU cloud features
Our GPU Cloud not only offers you access to the latest NVIDIA hardware – it is designed from the ground up to support your AI, HPC and visualization workloads with maximum efficiency, security and flexibility. As an NVIDIA Elite Partner with our own ISO 27001-certified data center in Germany, we combine technological excellence with data protection, availability and sound advice. You benefit from clear structures, fast provisioning and an infrastructure that is optimized for the most demanding computing requirements.
Direct access to NVIDIA B300 SXM6, RTX PRO 6000 SE, RTX PRO 5000 (72 GB and 48 GB), and H200 NVL. As an NVIDIA Elite Partner, we provide these systems reliably and quickly through our GPU Cloud.
Our infrastructure is specially designed for computationally intensive AI training, high-performance inference and sophisticated visualization applications. We support you with an optimized environment and expertise - including TensorRT support for maximum efficiency.
Find the right GPU in seconds: Our Hugging Face-based configurator automatically recommends the optimal hardware for training or inference. This saves you time and avoids costly mistakes.
Your data is in the best hands with us - thanks to hosting in our ISO 27001-certified data center in Limburg. We guarantee the highest standards of availability, protection and information security.
All data processing takes place exclusively in Germany and in compliance with European data protection regulations. This means that you retain full control over your sensitive information at all times.
Scale GPU performance to meet your needs at any time - whether in the short term for individual projects or in the long term for productive environments. Our clear pricing models ensure full cost control without surprises.
Our infrastructure offers optimized connectivity and fast data throughput - crucial for smooth training runs, fast inference and complex distributed computing processes. This allows you to avoid bottlenecks and delays when processing large volumes of data.
GPU power for your most demanding workloads
Whether AI training, real-time inference, high-end visualization or scientific computing – every application has individual requirements in terms of computing power, memory and efficiency. Our GPU Cloud offers you the right infrastructure for a wide range of scenarios and industries. Choose the optimal foundation for your projects from a broad portfolio of powerful NVIDIA GPUs – ready to use, scalable and reliably hosted in Germany.
Train large AI models on the Blackwell B300 SXM6—with maximum computing power and scalability for complex deep learning processes.
Take advantage of high-performance GPUs such as the B300 SXM6, H200 NVL, or RTX PRO 6000 SE for fast, low-latency inference in real-time applications and productive AI workflows—with high-throughput and low-latency serving.
Develop, train and optimize basic models efficiently - supported by flexible resources and specialized hardware for large-scale training.
Run computationally intensive simulations, financial analyses, or scientific calculations on the B300 SXM6 or H200 NVL with the highest precision and speed.
Choose GPUs such as the RTX PRO 6000 SE or RTX PRO 5000 for high-end rendering, CAD, VFX, digital twins, and demanding 3D applications.
Analyze medical image data, genome data or drug processes faster with specialized GPUs for data-intensive life sciences workflows.
Accelerate big data processing with GPUs for data-driven decision-making, machine learning and real-time analytics.
The decisive advantage for your business
With partimus, you benefit not only from state-of-the-art GPU technology, but also from a comprehensive offering designed specifically for demanding AI, HPC, and visualization applications. As an NVIDIA Elite Partner, we offer Blackwell and Hopper instances on top-of-the-line GPUs with short lead times, combined with expert consulting, intelligent GPU matching, and maximum security. Whether it’s rapid project implementation, long-term scalability, or data protection compliance—we lay the technical foundation so you’re always one step ahead of the competition.
As a certified NVIDIA Elite Partner, we offer you direct access to the latest high-performance hardware as well as prioritized support and technology updates.
Through our partnership with primeline solutions, we can provision Blackwell instances on short notice—with no waiting list and a predictable runtime.
From the RTX PRO 5000 48GB for individual inference workloads to a complete B300 system with eight GPUs—we have the right solution for every AI, HPC, or visualization project.
Our GPU configurator automatically analyzes your model and recommends the ideal hardware for you - quickly, precisely and independently of the manufacturer.
Your data is processed in our ISO 27001-certified data center in Limburg - fully GDPR-compliant and without third-country transfer risk.
Our entire infrastructure is consistently designed for maximum GPU performance for computationally intensive AI models and professional visualizations.
Get started with partimus
Take the opportunity to optimize your IT infrastructure and drive your business forward – contact us today to find out more about the tailored benefits partimus can offer you.
Everything you need to know about our GPU Cloud
Are you interested in using our GPU Cloud and still have questions about performance, selection or integration? In the following answers you will find specific information on availability, usage options and the technical advantages of our infrastructure. Our experts will also be happy to answer your individual questions by phone or email.
What advantages do I have over international cloud providers?
With partimus, you benefit from hosting in Germany, ISO 27001-certified security and strict GDPR compliance – with no hidden third-country transfer risks. You also get a direct contact person, personal advice and full control over your infrastructure.
Which GPU is right for my workload?
For large-scale training and memory-intensive inference, the B300 SXM6—with 192 GB of RAM per instance—is the most powerful option. The H200 NVL is suitable for large models with high memory requirements and offers a better price-performance ratio. For professional visualization, rendering, and low-latency inference, the RTX PRO 6000 SE and RTX PRO 5000 are the right choices. Our Hugging Face Configurator will provide you with a specific recommendation in seconds.
How do I find the right GPU for my project?
Our intelligent Hugging Face configurator recommends the optimum GPU in seconds – tailored to the model type, application (training/inference) and performance requirements. This saves time, reduces costs and ensures a tailor-made selection.
Which workloads can I run on the partimus GPU Cloud?
Our infrastructure is ideal for AI training and inference, foundation model development, HPC simulations, big data analytics and graphics-intensive applications such as CAD, VFX and digital twins – all scalable and ready for immediate use.
Can I flexibly scale and test GPU resources?
Yes. You can choose between 1, 6, 12, and 24-month terms and scale from one to eight GPUs per instance. Shorter terms are suitable for individual projects or proof-of-concepts, while longer terms significantly lower the monthly price. You can upgrade to a larger configuration at any time—just contact us.